A Government Organization Trained Language Model with Chinese-Hindi Translation

About the Client
A government organization focusing on building AI-powered NLP tools and translation engines for the Chinese markets, with strategic investments in machine translation, voice recognition, and document AI. They needed context-aware translation and aligned bilingual text for training, fine-tuning, and model benchmarking for large volumes of Data.
Challenge
The client’s multilingual engine struggled with poor performance for the Chinese-Hindi pair due to a lack of training data. The client required content from varied domains, but publicly available datasets were not domain-aligned and lacked contextual fidelity. Cultural and linguistic nuances are not captured in literal translations.
- Lack of clean, parallel corpora in Chinese and Hindi.
- Need for domain-specific content (finance, tech, government, media, etc).
- Inconsistent quality in existing open datasets.
Solution
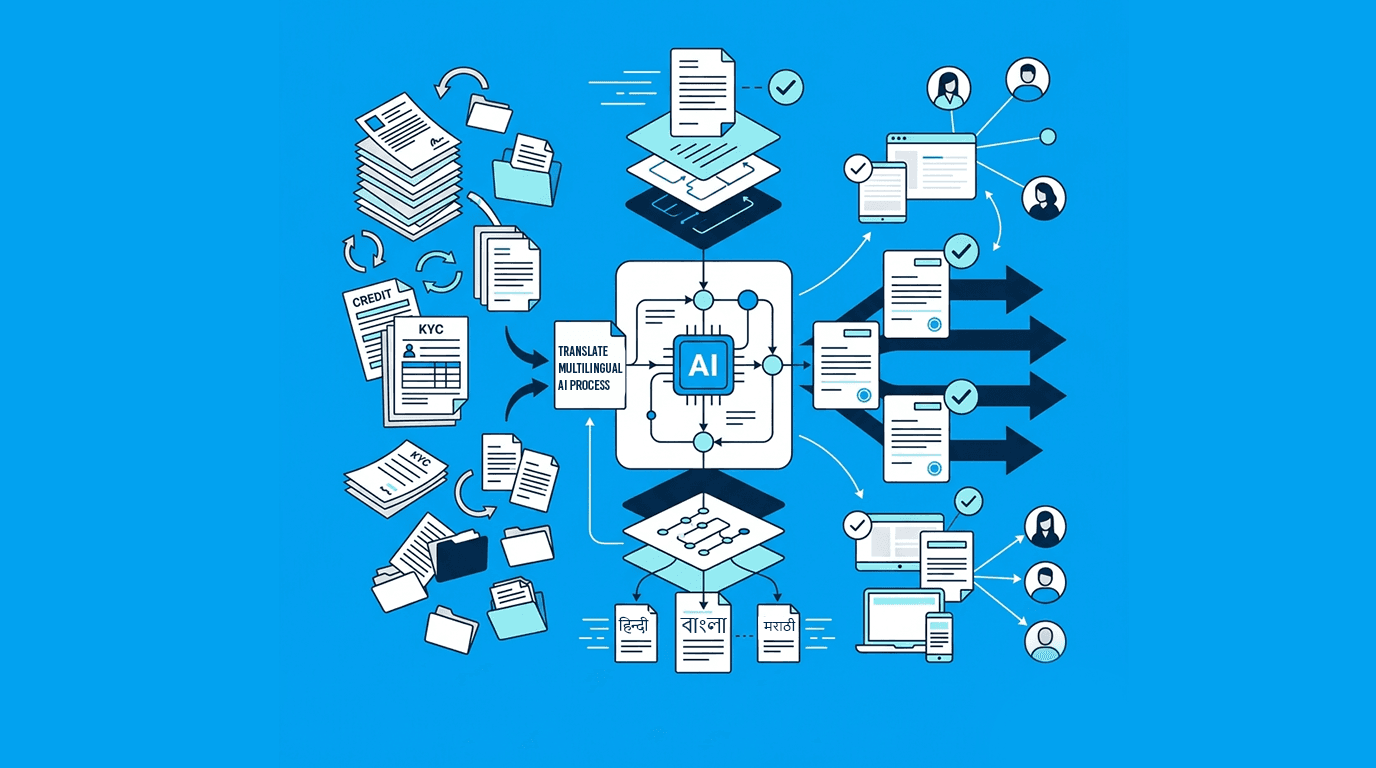
The Devnagri AI team set up a dedicated workflow to translate and align thousands of sentences and documents from Chinese to Hindi and vice versa across multiple domains. After assessing volume, format, and required domains with the client.
Implementation Steps:
- Built a project team of native and near-native translators and linguistic reviewers.
- Translated and post-edited over 500,000+ sentences.
- Applied consistency rules using translation memory and glossary tech.
- Delivered bilingual, aligned text files in client-ready format.
- Supported iterative review cycles with the client’s AI/ML teams.
Key Features
High-end AI-powered machine translation technology containing translation memory (TM) to maintain linguistic consistency.
Custom-built bilingual glossaries to ensure domain fidelity.
The linguistic quality assurance process includes random sampling and multiple review rounds.
The accuracy rate was consistently high in precision.
Result
Partnering with Devnagri, the client received a vast volume of accurately translated, domain-specific, and parallel text data, significantly improving model performance, recall accuracy, and translation fluency, thereby accelerating their roadmap.
- Delivered custom-translated, high-quality datasets between Chinese and Hindi.
- Maintained consistency, tone, and accuracy across domains.
- Enabled the client’s data scientists to use the corpus in model training with minimal cleaning effort.
- Improved the BLEU and TER scores of their translation engine.